Alongside deeproute we tried to teach a neural network to route boards the way people do. All in one day, 11 October, on rented H100 and H200 GPUs at Runpod.
Data: 52,233 KiCad boards from GitHub, GitLab, Codeberg and open benchmarks, 6.56 million routing steps. Each human trace is cut into steps "direction, length, layer or via", and the model learns to guess the next step. Boards similar to the test ones were removed, and Rabbit was never in the training set.
What we tried:
- a CNN over a 64×64 picture around the trace end: guesses the next step 72% of the time
- a ViT over the picture at three scales: 72.7%
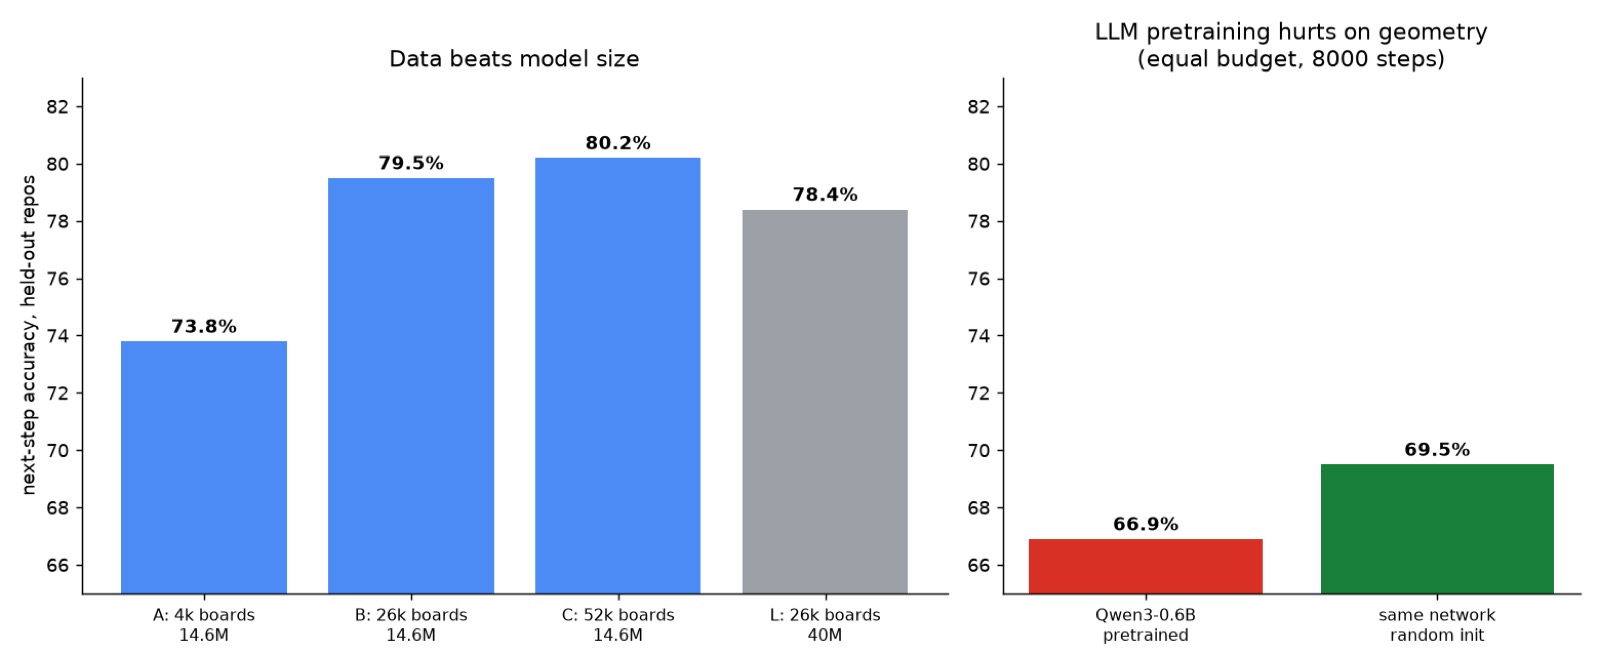
- RouteTok, a transformer over board objects (pads, tracks, vias) instead of pixels, 14.6M parameters: 73.8% on 4 thousand boards, 79.5% on 26 thousand, 80.2% on 52 thousand
- the same model at 40M parameters: 78.4%, worse than the small one
- Qwen3-0.6B as the backbone: 66.9% with pretrained weights, 69.5% from random ones. Knowing text only hurts on geometry
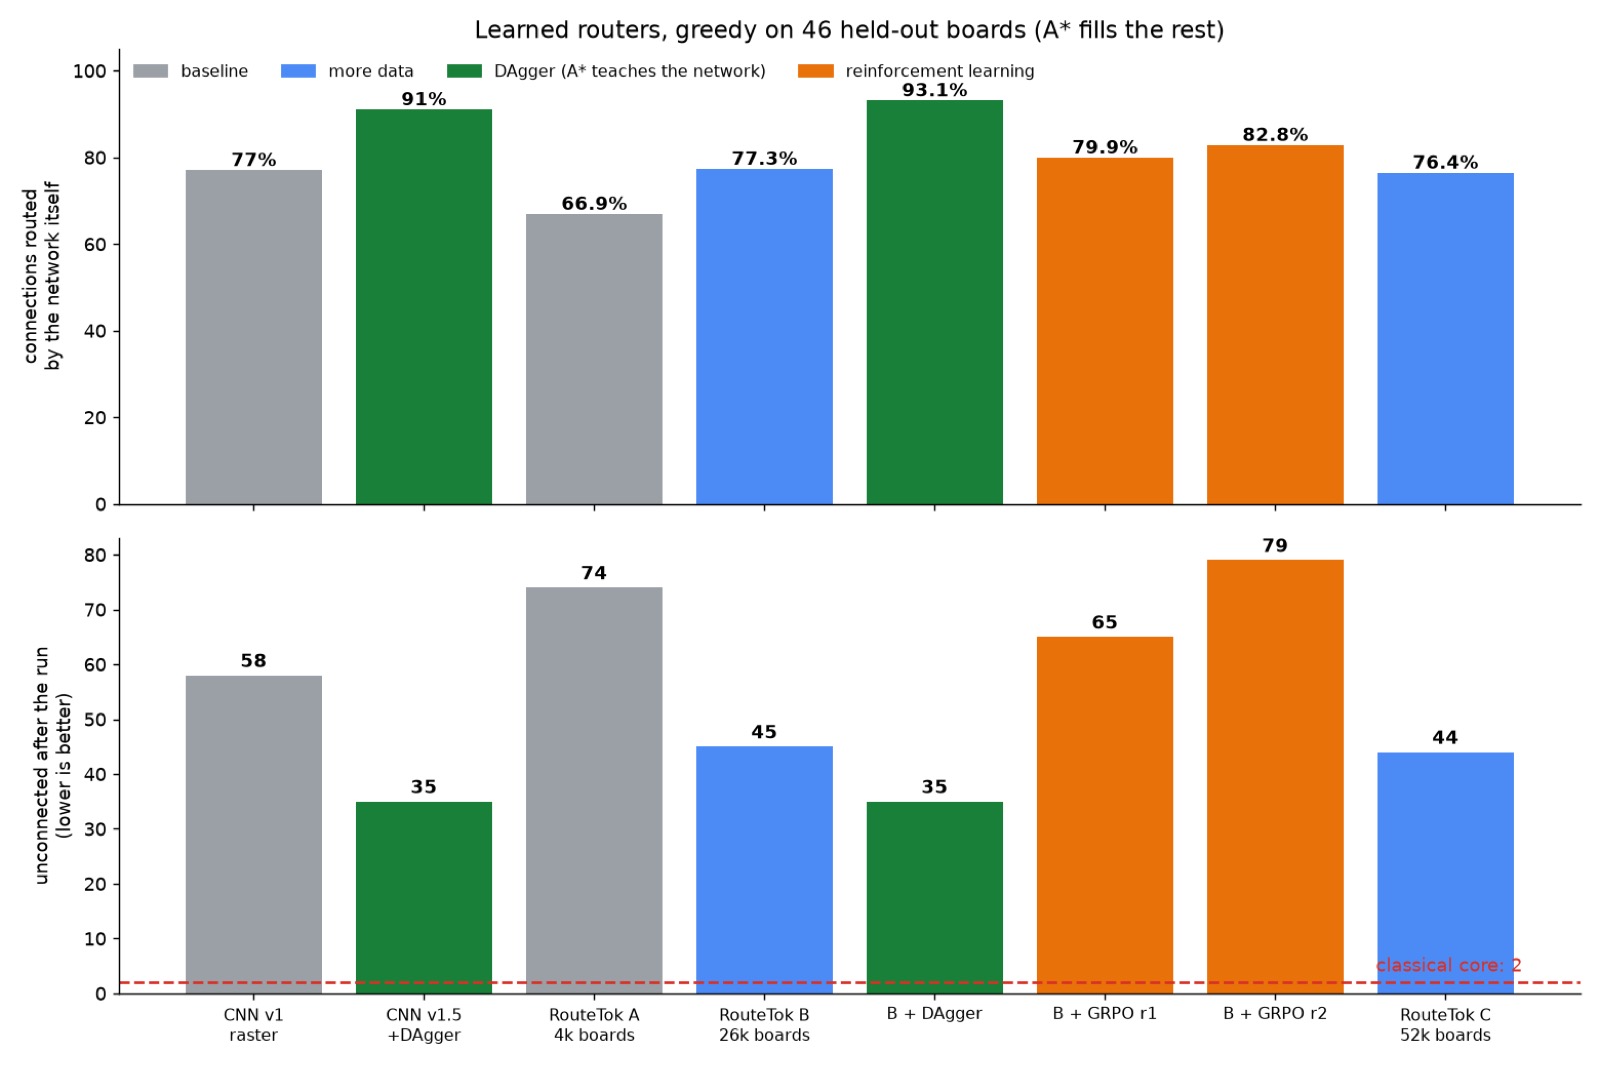
- DAgger: the model drives the trace and the classical A* says at every step what it would have done. The best thing that worked: the share of connections the network routes itself went from 77% to 93%
- GRPO reinforcement learning: the model routed more connections itself but took up space, and the board as a whole routed worse. Classic reward hacking
- an LLM writing coordinates as text: 45 times more tokens, about 2% of traces finished, dropped at once
The main lessons: data matters, not model size. Next-step accuracy says almost nothing about whether the model will route a board. And honestly: the best network leaves 35 unconnected on 46 test boards, the classical algorithm 2. So all of deeproute's records come from the classical core, and the networks remain a research branch for now.
The price of all this from the Runpod bill: $115.76, of which $103.69 for GPUs, about 23-24 GPU-hours (H100 about 17 hours, H200 about 6). One 14.6M model trains in about an hour on an H100 and costs a couple of dollars. Datasets on disk: 64 GB of raw boards and about 50 GB of prepared tokens.